Lesson 14 · Advanced · 15 min
Long context: process one million tokens in a single pass
Harness Gemini's massive context window: process 500-page dossiers in one pass and locate isolated facts without fragmented chunking.
- Goal
- You will ingest and query massive corpora spanning hundreds of pages in one pass to generate comprehensive, unfragmented executive syntheses.
- Skills
- Frame

Gemini's one-to-two-million token context window ingests entire enterprise document libraries without preliminary chunking or loss of nuance. To harness this massive capacity effectively, anchor critical guidance at both ends of the prompt and require exact page citations to neutralize attention drift across long texts.
1The death of chunking: holistic comprehension of massive files
The death of chunking allows teams to achieve holistic comprehension of massive files within a single analysis session. Gemini removes the artificial boundaries imposed by traditional retrieval-augmented architectures by retaining all source materials in active memory.
A one-million token context window accommodates roughly 750,000 words, equivalent to dozens of audit reports, regulatory binders, or complete software repositories. The model seamlessly correlates a footnote in volume one with a technical appendix in volume three without semantic loss. To prevent attention degradation across long documents (lost in the middle), structure your prompt by positioning primary constraints at the start and conclusion of the query.
Document analysis approach Traditional RAG architecture Native Gemini long context Operational advantage Source ingestion Chunked into disconnected fragments Ingests entire corpus in one piece Preserves distant causal dependencies Cross-volume synthesis Inconsistent across wide horizons Exhaustive across all sections Uncovers subtle cross-document contradictions Document setup Complex vector database indexing Direct upload of original PDF files Instant deployment without custom pipelines 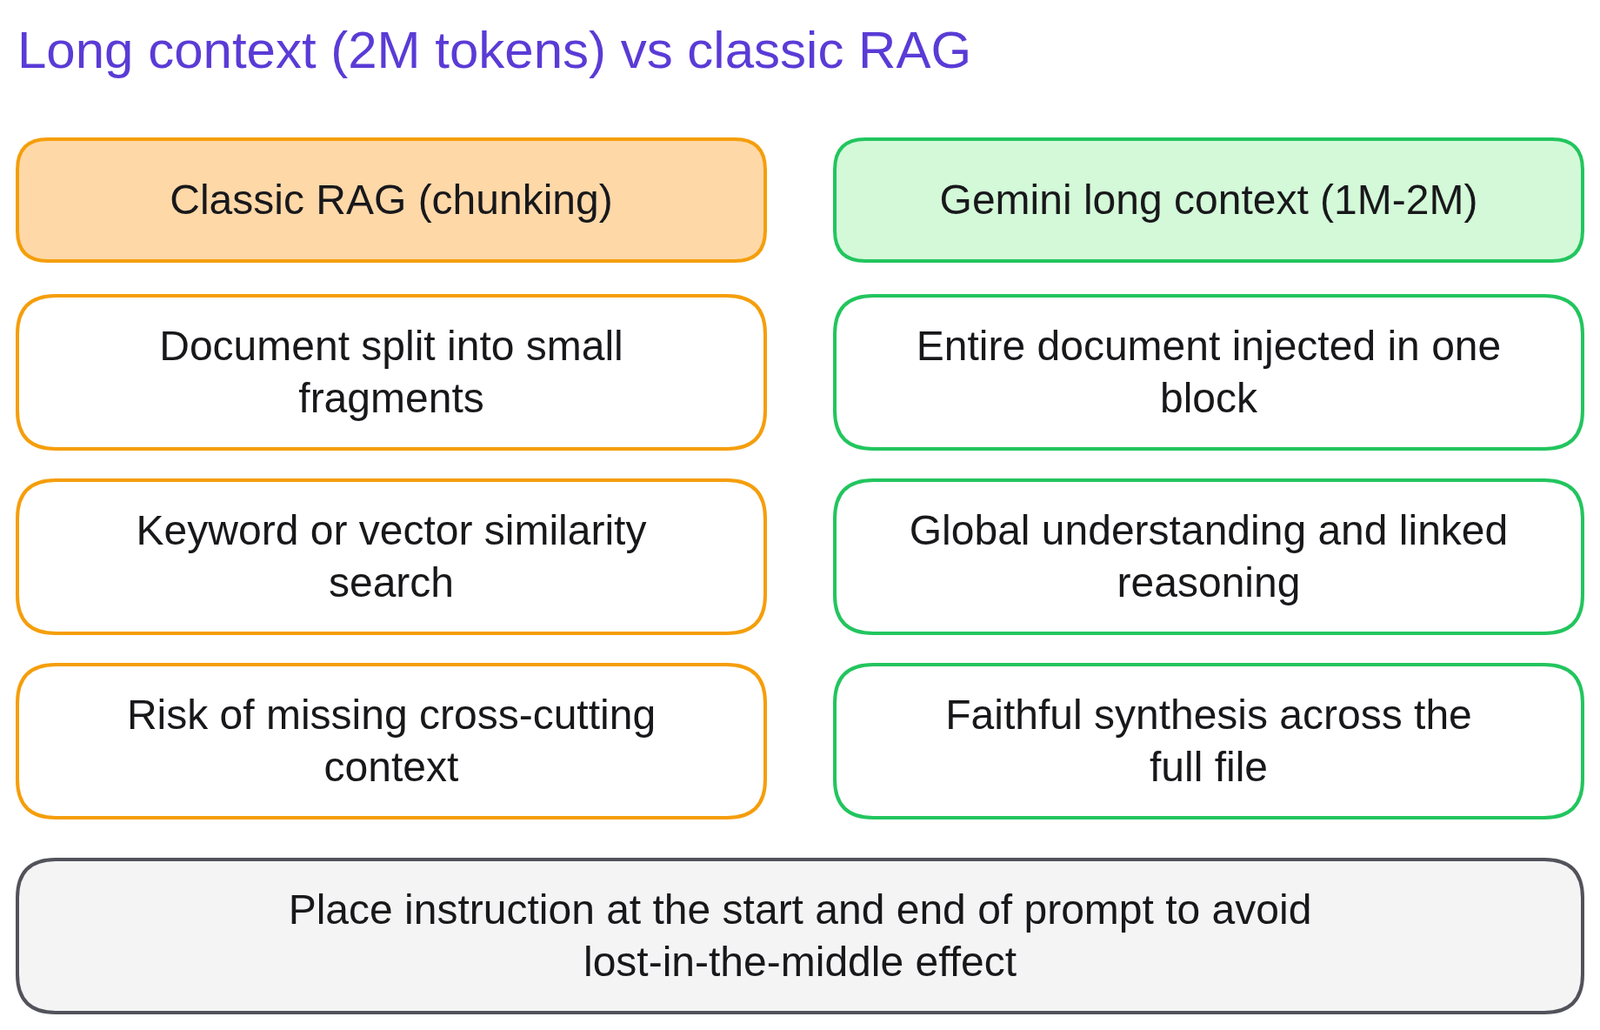
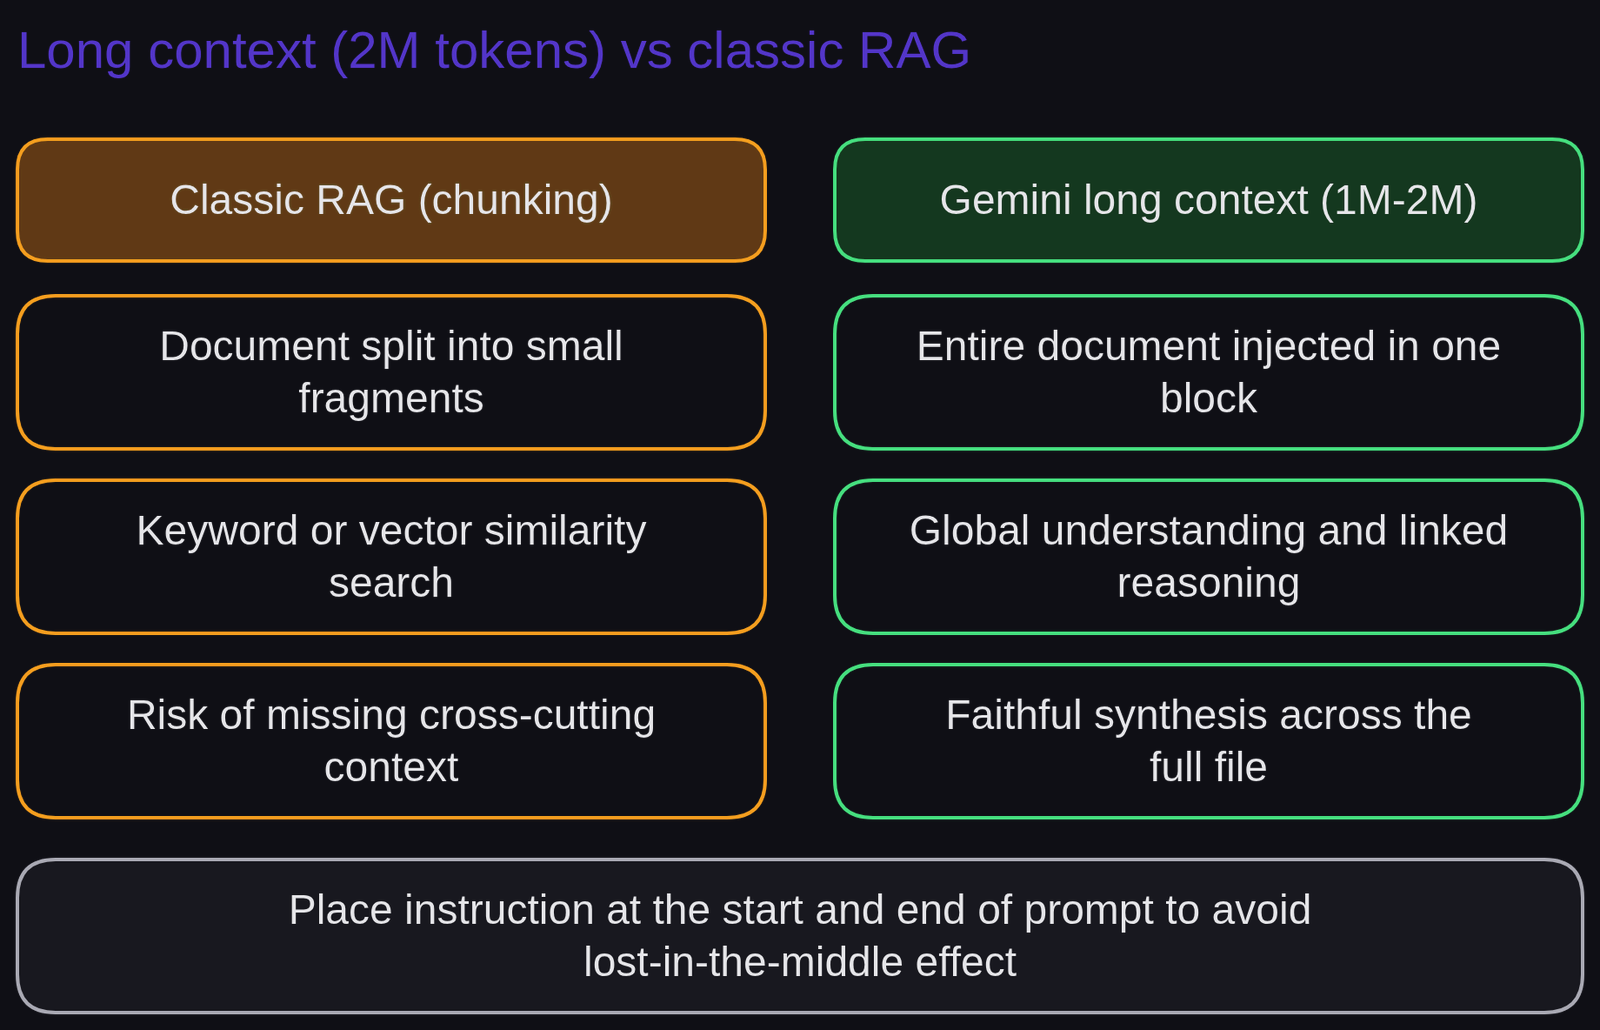
Diagram 'Long context vs traditional RAG'Diagram generated by AI and reviewed 2Cross-examining three distinct 150-page financial audit reports
Cross-examining three distinct 150-page financial audit reports demonstrates how Gemini massive context window identifies accounting discrepancies that escape fragmented manual reviews.
An internal audit director needs to compare asset depreciation schedules across three newly acquired European operating subsidiaries.
Weak prompt.
Here are three attached financial audit reports. Tell me if there are any differences between the subsidiaries.Gemini skims the documents, outputting a superficial summary of general business operations without highlighting specific accounting discrepancies.
Strong prompt.
Based on the three attached audit reports (Subsidiaries A, B, and C), construct a comparative table of depreciation timelines applied to fixed assets. Expected columns: Asset Category, Subsidiary A Schedule, Subsidiary B Schedule, Subsidiary C Schedule, and Identified Accounting Variance. Include exact source page citations in every cell. 130 words.The difference. The prompt confines the inquiry to specific accounting schedules and demands page-level citations, compelling the model to examine the full 450 pages with rigorous precision.
3Locating a documentary needle within a massive information haystack
Locating a documentary needle within a massive information haystack trains you to verify Gemini perfect recall across large corpora by posing an intricate inquiry requiring complete source comprehension.
To practice without handling sensitive records, here is an audit dossier excerpt (fictional company NovaTech Ltd), ready to copy or save into
audit_dossier.txt:[Acquisition Audit Dossier - NovaTech Ltd (Fictional Training Sample)] Section 12 - Off-Balance Sheet Commitments & Asset Guarantees: Outstanding bank guarantees issued to operating subsidiaries stand at €1.4M as of December 31, 2025. Section 18.4 - Environmental Remediation Clause: Any environmental remediation costs exceeding €250,000 excl. VAT on the logistics hub remain the sole liability of the seller for 36 months following transaction closing. Appendix C - Exceptional Delay Penalties: In the event of extreme severe weather emergencies officially recognized by government decree, contractual delivery delay penalties are suspended without compensatory indemnities. (Audit Note: no derogations are granted for internal technical system failures).The "Load exercise" button in the composer pre-fills the objective with the weak starting prompt:
"Locate in the dossier the clause regarding exceptional penalties and quote it verbatim."
From this starting point, complete the prompt with the composer: specify the source document (
audit_dossier.txt), require exact verbatim quotations referencing the parent section, enable the "not found" fallback for unstated facts (test a query on employment tribunal disputes), and apply the end-instruction technique (arXiv:2307.03172): position your precise instructions at the very end to maximize recall accuracy across long contexts.Self-evaluation rubric: (a) the source exhibit and appendix are accurately identified; (b) the 25-word excerpt is transcribed verbatim; (c) the end-instruction format delivers focused retrieval without conversational filler.
4Loosening prompt discipline assuming the model automatically knows what matters
Loosening prompt discipline assuming the model automatically knows what matters produces superficial outputs, as massive context without targeted boundaries dilutes analytical focus.
The larger the uploaded corpus, the more surgical your prompt constraints must be. Requesting a 'general summary' of a thousand-page dossier causes Gemini to return generic platitudes while missing subtle risks buried inside technical appendices.
Fix: frame targeted inquiries specifying exact operational perspectives, entities to cross-examine, and expected table schemas.
Rule to remember: massive source volumes demand heightened prompt precision to avoid semantic drowning.
5Quiz
Three questions, instant feedback. Each option comes with an explanation.
6Proof of mastery
Ingest a collection of documents exceeding 100 pages combined into Gemini and generate a cross-comparative brief citing page numbers from at least two sources.
Criteria


Going further
Examine glossary entries for context window, RAG, and in-context learning. The next lesson, Analyze a video with Gemini, applies long context across temporal multimedia. To build persistent organizational repositories, explore Create a custom Gem.
Frequently asked questions
What does one million tokens represent in practical terms?
One million tokens equals roughly 750,000 words, representing around 1,500 pages of text, one continuous hour of raw video, or over 30 hours of audio recordings.
What is the 'Needle in a Haystack' benchmark?
It is an evaluation measuring whether a model can retrieve an isolated factual needle planted anywhere within a massive corpus. Gemini achieves recall accuracy exceeding 99% across its window.
Does long context render RAG obsolete?
For focused dossiers spanning hundreds of pages, long context beats naive RAG pipelines. For enterprise knowledge repositories indexing millions of files, vector retrieval remains necessary for initial filtering.